Tags: deep learning State: mature
NOTE: I am here focusing more on the attention equations and its interpretation
In the paper a single head of attention takes Q, K, V matrices and does a matrix multiplication between Q and K. Q is the query matrix and K is the key matrix
A good intuition to have is that Q matrix is the matrix that asks what is the word that will influence me. The way we give a value to influence is by doing a similarity multiplication (dot product) between Q and K
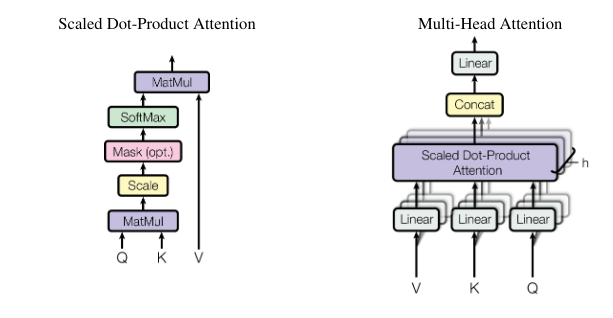 The best way to look at his that in the beginning we initialize Q, K and V to the input embedding and then we pass them through a feed-forward network with no bias - which basically is a matrix multiplication - and we get the Q, K and V matrices. The paper did not specify how did we get Q, K and V, or that we initialize them to the inputs before passing them to a linear network, which made it a bit confusing to me at the beginning
The attention equations are where