tags: cuda programming, programming, deep learning
What is meant by “full semantics of a CUDA thread” ?
According to ChatGPT: “The phrase “full semantics of a CUDA thread” refers to the ability of CUDA threads to behave as if they are executing independently, even though they are executed in groups (warps) on Single Instruction, Multiple Data (SIMD) hardware.”
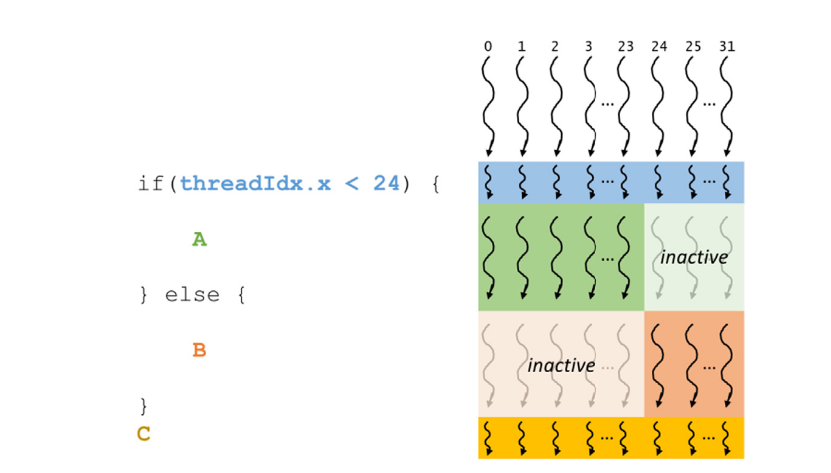
So when there is different flow in a CUDA kernel, it appears that every thread is running on its own, every thread is getting its own instructions and running and doing all its computation with its own instruction fetcher, but in reality that is not correct.
In reality, SMs are divided into processing block in which they have some cores that share the fetch instruction unit. This unit fetches the instruction and runs it on all the threads in the warp, but what happens during branches ? well it first runs a branch, masking the threads that will not run this branch and then does the opposite
Another way I’d like to think about this, is the fetcher fetches the instruction, sees which threads satisfy the condition to execute the instruction and executes these threads while making the others in active.
Best explained here: